Yet another update on the running AI discussion.
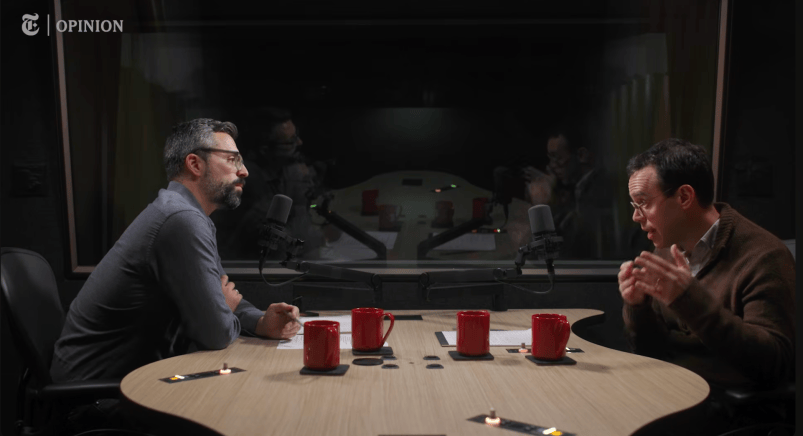
Here’s an interview Ezra Klein did with a guy named David Robinson. And that interview is about a piece Robinson, a member of the Open AI safety and safety documentation team, wrote in The Atlantic announcing his resignation from OpenAI — a decision and announcement he is self-aware enough to note has become something of a cliche. I found the interview interesting and edifying, largely on the front I mentioned earlier about finding reliable narrators.
Robinson isn’t a data scientist or a programmer. His role at OpenAI was essentially being the conduit between the teams building the LLMs and the knowledgable and interested public, specifically the people who write the documentation — what does this model do, how does it work, what are the possible safety risks. As is usually the case in any highly technical space, the people doing the work aren’t going to be writers and they’re usually not going to speak a language outsiders can necessarily understand. So you have people who are close enough to the work and the workers to understand what is happening and also able to speak human so they can communicate it to everyone else. Robinson led the team that served in that role.
What makes his perspective interesting is that from his self-explanation and what I can tell he doesn’t come out of the Silicon Valley world or what I’ve called the “REL world.” He seems to basically come out of the highly-educated world, with points of contact with D.C. and the non-Silicon Valley think tank community. The pieces I’ve been writing recently basically align with the folks who are skeptical both of AI triumphalism and doomerism. Robinson says he went into OpenAI in 2023 basically with that worldview. But having worked there for the last three years, he’s decided that he can’t be sure the REL folks’ arguments about major, catastrophic risks aren’t valid, whatever path they may have chosen to get there. In the abstract, at least, that’s the perspective I’ve been looking for — someone who I don’t think is definitionally unreliable but who has actually seen what’s happening from something like the inside. I recommend watching it or listening to it.
There’s definitely some of the discussion that comes off a bit precious. But again, I think I learned something from it and you may too. Robinson’s basic argument is that government regulation is required, and we need to be treating advanced AI models with a framework similar to those we apply to nuclear power or aviation, which is to say a regulatory approach heavily weighted toward safety given the stakes for unsafe behavior. This seems eminently reasonable to me. What one might call the minimum point of agreement in the broader AI discussion is that there’s a lot of dangerous or reckless behavior; whether that’s inherent in advanced AI research and we’re inevitably racing toward the “singularity” or whether these teams are just reckless and sloppy, sort of same difference in terms of a policy response.
One impression I had, or one possibility I considered, is that it’s hard to work somewhere for three years and not internalize a lot of its assumptions. I picked up at least some of that in Robinson’s and Klein’s discussion of “intelligence” and “rogue behavior.” But again, not so much so that I didn’t find their conversation useful or his perspective edifying.
Lots of the discussions about AI and AI safety turn on this question of “alignment,” which is industry shorthand for AI that behaves as we expect and/or in line with human values. What I’ve come away with is a strong sense that the whole idea is, to use technical language, wildly under-articulated, or that it simply makes no sense and is kind of impossible. That’s partly because what counts as “intelligence” and “human values” are way more complicated and amorphous than these discussions allow for.
At a fundamental level, LLMs work in unpredictable ways because you can’t really know just what you’re training them to do or what kinds of actions you’re incentivizing them to take. I think I’m on pretty strong ground making that claim, and it’s worth absorbing what that means. That doesn’t mean they’re “minds” which will decide to do things we didn’t tell them to do. We just don’t know what we’re telling them to do. So the whole idea of them “going rogue” is just a non sequitur. It’s like saying my paint went rogue because it didn’t dry right after I used the wrong kind of paint. One of the key testing regimens AI labs apply to these models is how to hack, or simply how to solve a certain problem. They create tons of incentives to accomplish the task, throw unimaginable amounts of computing power at it, and then it solves the problem in a way they didn’t expect. But that shouldn’t be surprising since we don’t actually know what we trained them to do. “Alignment” kind of amounts to a global version of Bill and Ted’s “be excellent to each other” motto, and thinking that this intention is going to unravel the tangled skein of ‘We don’t actually know what we taught them to do in the first place.’ But that seems like an engineer-minded solution to something that isn’t engineerable, at least on one level and maybe at three or four different levels.
What I think this amounts to is that we’ve developed technology that is at least very good at devising solutions to bounded tasks (capture the flag, find the answer, hack the machine) but acts in inherently unpredictable ways. And we keep turbocharging those models to be able to act faster and faster and devise more and more inherently unpredictable ways to act. You don’t need to have any wacky ideas about tech-utopianism or tech-doomism to think that might have bad outcomes.
I’m really not convinced that what folks in this world call “super intelligence” is really that at all, or that a lot of their other concepts make sense. But I don’t think you need that to decide this is reckless behavior that society needs to exert some control over. I think that’s at least broadly in line with what Robinson is telling us even if he comes to that conclusion in somewhat different ways or with different language.